Originality in AI research: what’s at stake
You can read an AI paper and feel two things at once: the results look impressive, and yet the ingredients feel familiar—same benchmark, same pretrained backbone, a slightly different training recipe. That tension matters because “original” is doing real work in how we fund research, hire people, publish papers, and decide what to trust. If we label every incremental tweak as a breakthrough, we encourage shallow novelty and burn time chasing leaderboard gains. If we dismiss careful extensions as “just remixing,” we undervalue the work that makes methods reliable, comparable, and usable outside a single demo. The stakes are credibility and progress.
What counts as “original” in science anyway?
Think about how most science actually moves: rarely by inventing everything from scratch, more often by changing one meaningful piece of a shared setup and showing that the change holds up. Originality usually means a defensible contribution—something that wasn’t already implied by the prior literature and that others can learn from or build on. That contribution can be a new question worth asking, a method that reliably improves a capability or reduces a known failure mode, evidence that challenges an accepted claim, or a synthesis that makes previously separate ideas work together.
At the same time, “original” is not a vibe. It has to be legible against a baseline: what stayed the same, what changed, and why the change matters beyond a single plot. In AI, the practical cost is that proving this often requires extra ablations, robustness checks, and reruns—work that is time-consuming and sometimes expensive.
The thin line between building on work and copying
In AI, reusing a backbone model, a dataset, or a well-known training pipeline is normal, but it also makes it easy to hide behind inherited strength. The line starts to blur when a paper changes only surface details—one hyperparameter sweep, a different prompt template, a small architectural knob—and then presents the outcome as a new idea rather than a better-tuned baseline. Another warning sign is when the “contribution” is mostly packaging: a new name for a combination that prior work already described, with no clear argument for what the synthesis reveals or enables.
Building on work earns its keep when the authors show what the borrowed pieces do not already guarantee. That usually means a crisp delta (what is new and why), direct comparisons to the closest prior implementations, and evidence that the effect persists beyond one benchmark or seed. This is costly: rerunning strong baselines, reproducing competing code, and testing across settings can take weeks of compute and engineering time.
Where AI can add novelty: methods, questions, and surprises
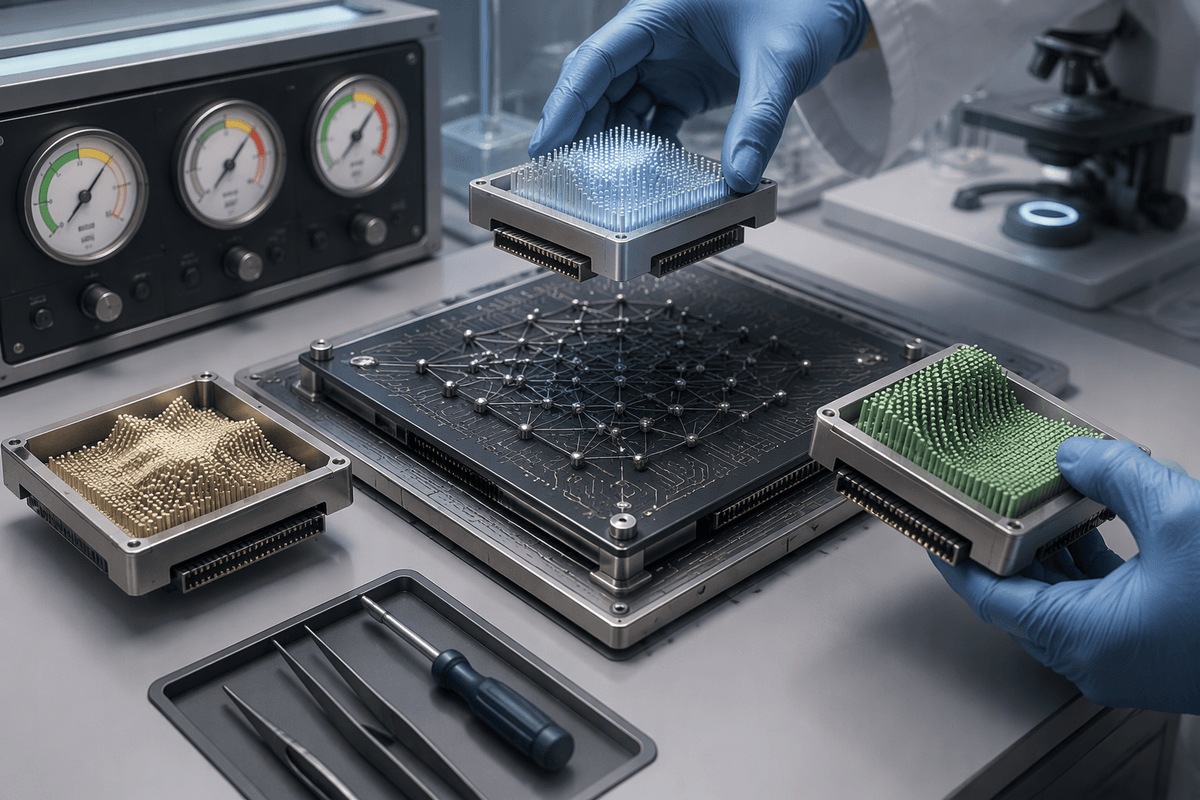
A familiar pattern in AI papers is that the backbone stays fixed and the “newness” shows up in how it’s used. Method novelty can be real even when everything looks reused: a training objective that makes failures measurable, an inference-time procedure that trades a bit of latency for much better reliability, a data curation rule that reduces a specific bias without collapsing accuracy. The tell is whether the change exposes a controllable mechanism—something you can reason about, not just a lucky configuration.
Question novelty is often underrated. Taking a standard model and asking a sharper question—does it generalize under distribution shift, can it explain its uncertainty, what breaks under multilingual inputs—can produce original evidence even if the architecture is unchanged. “Surprises” also count when they’re pinned down: unexpected scaling behavior, a negative result that overturns an assumption, or a simple combination that works for a non-obvious reason. Turning a surprise into knowledge usually requires extra runs, diagnostics, and stress tests that many teams can’t afford.
Constraints that limit originality: data, incentives, and evaluation
You can often predict what a paper will look like just by seeing what data and models are easiest to access. If the field mostly shares a handful of large benchmarks and a few dominant pretrained backbones, many projects become “find a trick that moves this number” rather than “ask a new question.” Data collection is a hard bottleneck: getting high-quality labels, sensitive-domain permissions, or multilingual coverage can take months, and the cheapest option is to stay inside public datasets even when they no longer represent real-world use.
Incentives narrow the search space further. Conference deadlines reward fast iterations and clean wins, not messy explorations where the first result is negative or ambiguous. Compute budgets also tilt what counts as feasible originality: some ideas need repeated runs, broad ablations, or many tasks to prove they’re not a fluke, and that can be out of reach for smaller labs. Evaluation adds its own gravity; when success is defined by a leaderboard metric, researchers optimize for that metric’s blind spots, and “original” quietly becomes “measurable.”
How to judge an “original” AI research contribution
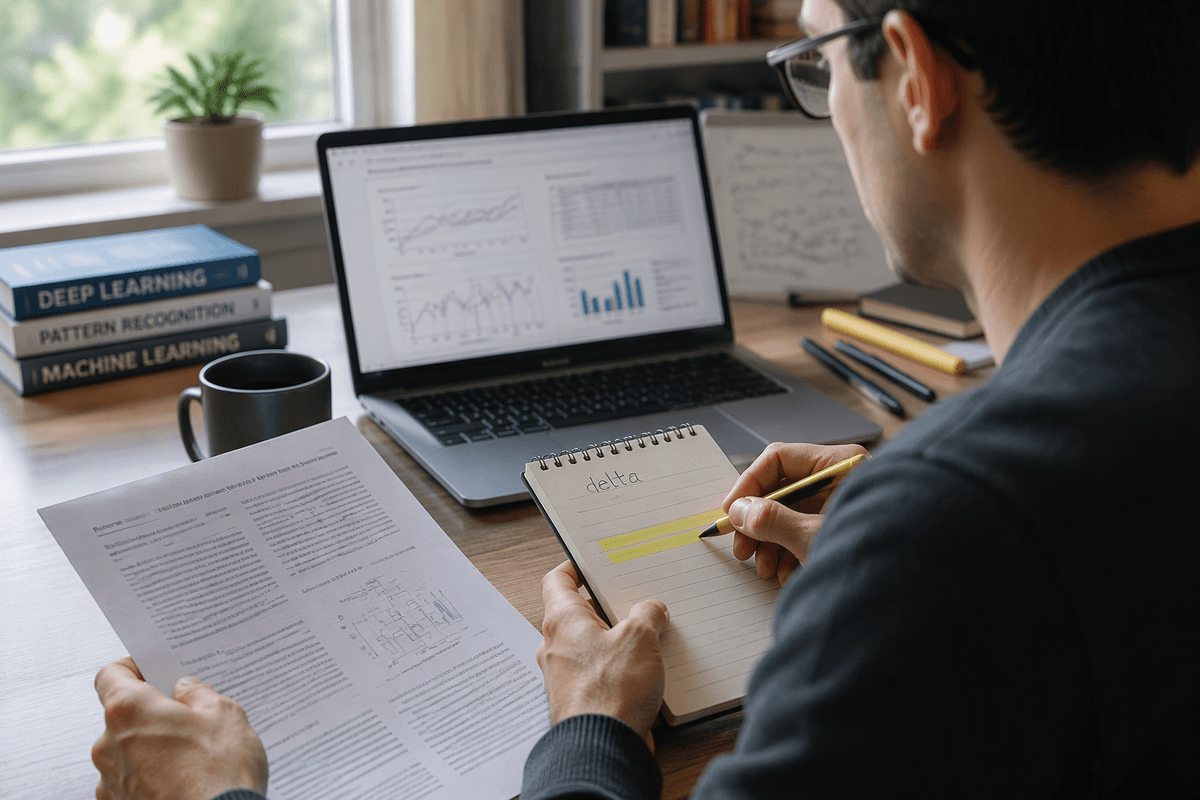
Picture skimming a new paper and trying to decide whether it’s a real step or a cleanly written retread. A practical test is to force the “delta” into one sentence: what changed compared to the strongest reasonable baseline, and what can someone do now that they couldn’t do before? If the delta is mostly “we tried harder” (more compute, more data, more tuning) without a mechanism or a lesson that transfers, the originality is thin even if the score is higher.
Then check whether the authors earned the claim. Look for direct comparisons to the closest prior methods (not just older ones), ablations that isolate which ingredient matters, and sensitivity checks across seeds, datasets, or model sizes. Also look for a well-defined failure mode the work reduces, or a new evaluation that reveals something hidden by standard benchmarks. Truly convincing evidence often requires reruns, careful baseline reconstruction, and broader testing than many teams can fund, so papers sometimes overclaim from narrow evidence.
A practical view: originality as a continuum, not a miracle
You’ve probably seen two papers that reuse the same backbone and benchmark, yet one feels clearly new and the other feels like a rename. That’s because originality is rarely binary. It’s a continuum from “competent extension” (clear delta, careful baselines, useful negative results) to “conceptual step” (a new question, mechanism, or evaluation that changes how others work). A good habit is to score contributions separately: novelty of the question, novelty of the method, and novelty of the evidence. If only one moves, that can still be valuable—as long as the limits are explicit and the gains aren’t just more tuning or compute.