When the model “knows” language, but not yours
You’ve probably seen the pattern: a model writes smooth English, then stumbles on a smaller language, a regional variant, or a document full of industry shorthand. It can feel like “it knows language,” yet somehow doesn’t know the way your users actually speak or write. That gap often shows up as mistranslated names, flattened tone, or technical terms replaced with something more common and slightly wrong.
What’s happening is less mysterious than it looks. The model learns statistical patterns from what it was shown, and “a language” is not one thing in practice—it’s dialects, spelling conventions, borrowed words, and domain habits. If your version of the language appears less often in training data, the model will default to the nearest patterns it has seen more frequently. That default can sound fluent while quietly drifting away from your meaning, which is why human review and domain-specific guardrails still matter.
Data scarcity: the biggest bottleneck nobody sees
A familiar failure case is a short sentence that should be easy, but the model “fills in” a different verb form, swaps a local place name for a more common one, or chooses the wrong sense of a term that looks similar in a bigger language. That often traces back to a simple constraint: your language variety, writing style, or domain just doesn’t show up enough in the data the model learned from. Even when a language is technically “supported,” the model may have seen far more casual chat than contracts, far more blog posts than clinical notes, and far more standardized spelling than what people actually type in the real world.
The unevenness isn’t just about quantity. A lot of available text is noisy—auto-generated pages, low-quality translations, duplicated content, or scraped fragments with missing context. Curated, high-signal data (good parallel translations, verified terminology, labeled examples) is expensive to produce and often restricted by privacy, licensing, or regulation, especially in medical and legal settings. When the clean examples are scarce, the model learns broad patterns but misses the edge cases your users care about most.
Tokenization and spelling variations break words apart
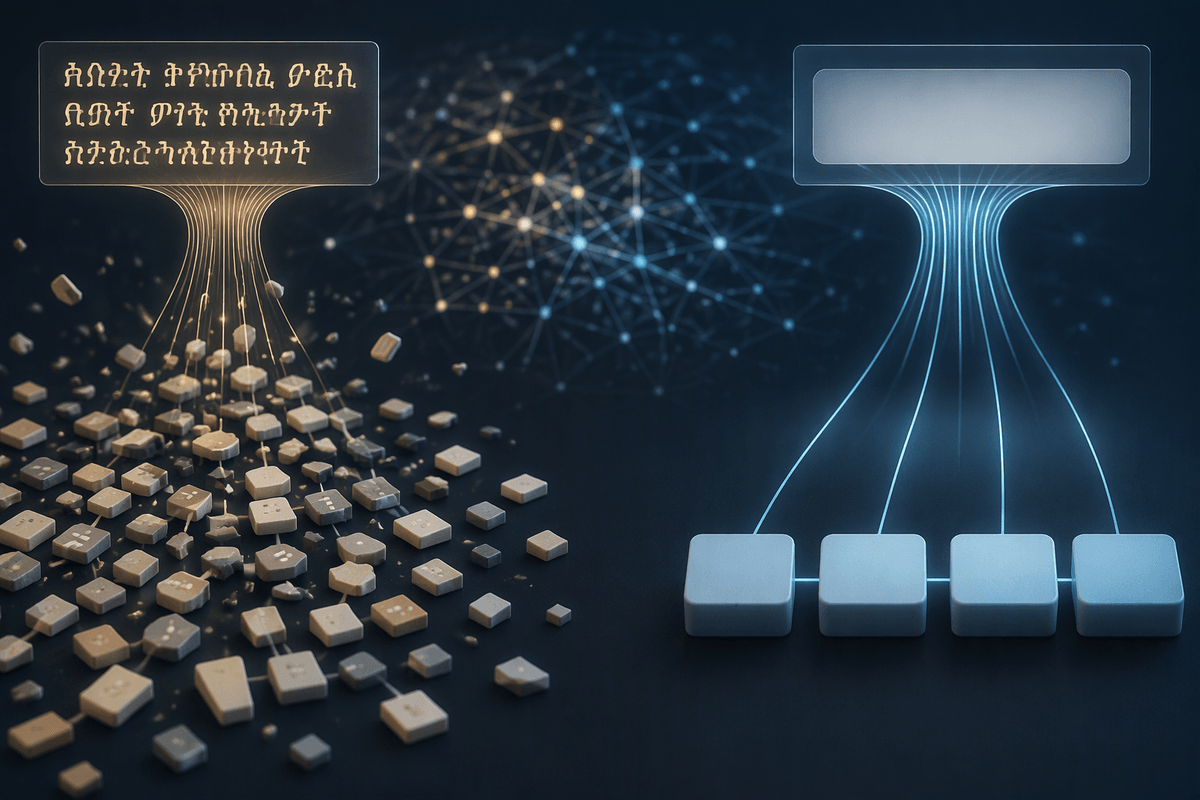
You can also run into a quieter issue that looks like “the model doesn’t know this word,” even when it does: the word gets split into awkward pieces before the model ever starts reasoning. Most modern models don’t read text as whole words. They break text into tokens—common chunks they’ve seen often. In high-resource languages, frequent words tend to be represented cleanly. In less-common languages, new compounds, or domain terms, the same string may be chopped into many rare fragments, which makes it harder to keep meaning stable across a sentence.
Spelling variation amplifies this. A hyphen, diacritic, alternate transliteration, or a local abbreviation can produce a totally different token sequence, so “the same term” stops looking the same to the model. Normalizing spelling, choosing one standard form in a glossary, and keeping key terms consistent across prompts can help, but it adds workflow cost and doesn’t fix inputs you don’t control.
Specialized vocabulary needs context, not just definitions
A product team often tries the obvious fix: provide a glossary. Define the term, list approved translations, and hope the model follows it. That helps with simple substitutions, but specialized vocabulary is rarely a one-to-one mapping. “Discharge” in a hospital note, “discharge” in an electrical spec, and “discharge” in a legal order can share a surface form while requiring different verbs, surrounding phrasing, and even different implied actors. When the surrounding context is thin, the model reaches for the most common sense it has seen, and the output can be fluent while landing in the wrong domain.
Context also includes document conventions: section headers, boilerplate clauses, units, and the typical way professionals hedge uncertainty. Without examples that look like your real inputs, “definitions” become brittle rules the model fails to apply consistently. Adding this context costs time: you need representative snippets, consistent formatting, and sometimes human-reviewed exemplars, not just a term list.
Evaluation blind spots: errors don’t get caught early
A common surprise is how long these problems can persist inside a product, even with frequent use. Teams test on a handful of sample prompts, scan for glaring mistakes, and move on. But smaller languages and domain text often fail in ways that don’t look “broken” at a glance: a plausible synonym that changes liability, a unit silently converted, a negation dropped, a person’s name normalized into a more common spelling. If nobody is measuring those specific failure modes, they don’t show up as regressions.
Evaluation also tends to overfit to what’s easy to score. Generic benchmarks rarely match your dialect, your formatting, or your terminology, and automated metrics can reward fluent paraphrase while missing meaning drift. Building a real test set means collecting representative documents, getting expert labels, and updating it as writing conventions change. That work is slow, sometimes legally sensitive, and usually competes with shipping features, so the model’s weakest areas stay invisible until a user reports them.
Why the model sounds confident when it’s wrong
The output often looks polished right up to the point where it’s wrong. That’s because the model is optimized to produce the most likely continuation of text, not to “show its work” or stop when it’s unsure. In a low-resource language or a narrow domain, the model may only have weak signals, so it leans harder on generic patterns: common phrasing, familiar sentence shapes, and widely seen meanings of ambiguous terms. The result reads like a confident professional draft, even when it has quietly guessed.
Product tuning can amplify this. Systems are often trained to be helpful, direct, and complete, which nudges them away from hedging or asking clarifying questions. If your prompt invites a definitive answer (“translate,” “summarize,” “extract”), the model will usually comply, even when the input is under-specified or tokenized into fragments. Making it less overconfident is possible, but it comes with trade-offs: more refusals, longer interactions, and added review time when you need speed.
Practical ways to get better results today
A familiar scene: you paste a clause-heavy contract excerpt or a lab note in a smaller language, get something that reads well, and only later notice a single term flipped the meaning. The quickest mitigation is to treat the model like a fast first draft: constrain the task (“translate, keep names and numbers unchanged, preserve section headings”), and include a short, consistent glossary with preferred spellings and “do-not-translate” tokens. When you can, provide one or two high-quality in-domain examples in the same format as the real input; that often beats longer instructions.
Operationally, add friction where it matters. Route high-risk outputs (medical dosing, legal obligations, safety procedures) to human review, and build a small “red flag” checklist: negations, units, dates, and domain keywords that must match. If volume justifies it, invest in a targeted evaluation set and lightweight fine-tuning or retrieval of approved terminology, but plan for ongoing costs: data curation, privacy review, and periodic re-validation as writing conventions shift.