Why sampler settings change results so much
You’ve seen it: the same prompt produces a crisp, on-topic answer once, then a meandering or oddly phrased answer the next time. That isn’t just “model randomness.” Generation is a step-by-step process where the model scores many possible next tokens, and sampler settings decide how many of those candidates are allowed to compete and how aggressively the choice favors the top option. Small parameter changes compound across dozens or hundreds of steps, so the final output can drift in meaning, tone, and structure.
Those settings also trade off different failure modes. Narrow sampling can lock you into safe but generic phrasing, or get stuck in repetitive ruts. Wider sampling can add creativity but increase off-topic jumps and subtle factual errors. Tuning often means running multiple test prompts and comparing outputs, not just changing one knob once.
Define “good output” for your specific task
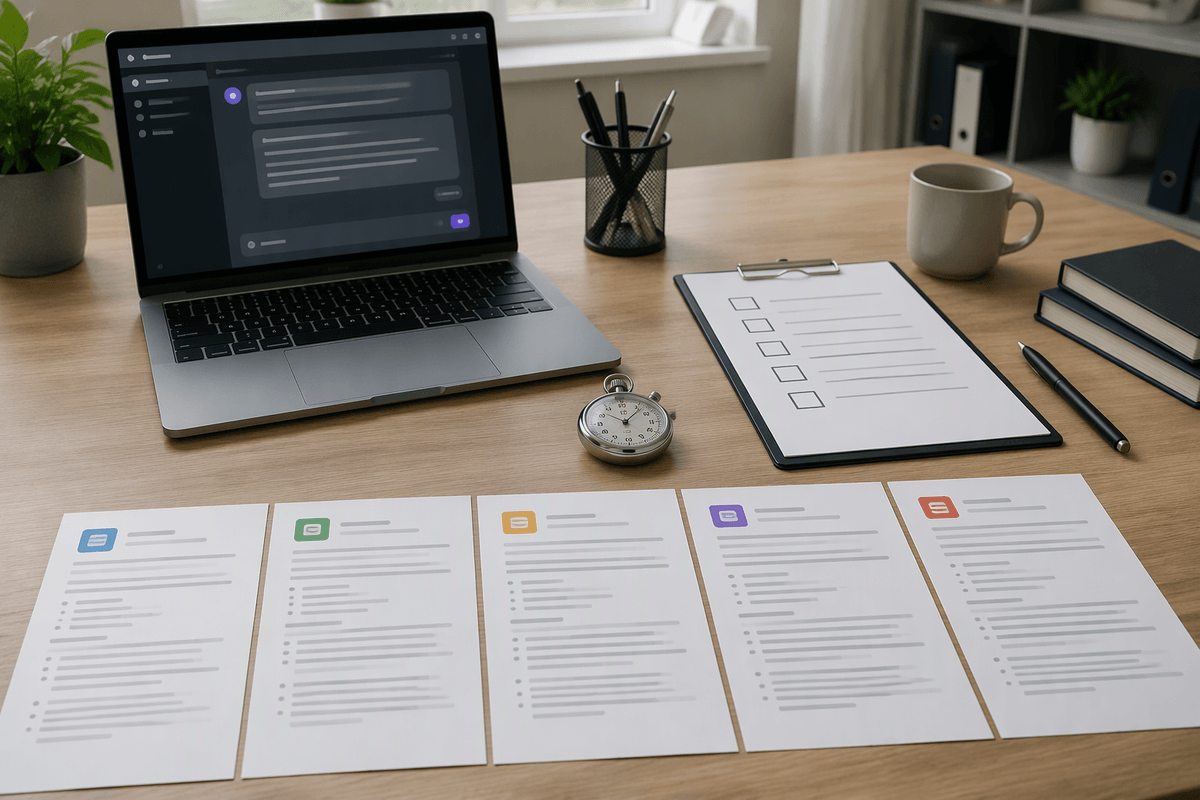
A common trap is tuning temperature or top‑p before you’ve decided what “good” means for this job. In practice, “good” is a checklist you can apply to five sample outputs in under a minute: correctness (no invented details), task fit (answers the question you asked, not a nearby one), format (JSON that parses, bullets that stay bullets), coverage (hits the required points), and voice (matches the product tone without sounding like boilerplate). If you can’t score outputs consistently, you can’t tune consistently.
Make the criteria concrete and testable. For a support draft, you might require: acknowledges the user’s issue, asks at most one clarifying question, offers two actionable steps, and avoids policy claims. For code generation, you might require: compiles, uses the specified library, and doesn’t change function signatures. These constraints often reveal the real trade-off you’re willing to pay—less variety to gain fewer retries, or more variety to explore better phrasing—before you touch any sampler knob.
Temperature vs top‑p: similar feel, different control
You can feel temperature and top‑p as the same kind of “creativity dial,” because both change how willing the sampler is to pick a less-likely next token. The difference is what they hold constant. Temperature reshapes the whole distribution every step: higher temperature flattens the scores so more tokens become competitive, and lower temperature sharpens the gap so the top choice dominates. That makes temperature a blunt but predictable lever when you want “more daring” or “more literal” across the entire response.
Top‑p (nucleus sampling) instead draws a moving boundary: it only allows the smallest set of tokens whose cumulative probability reaches p, then samples inside that set. When the model is confident, that set is tiny and behavior stays tight; when the model is uncertain, the set grows and behavior loosens. Practically, top‑p often preserves reliability on easy parts of a prompt while still exploring on ambiguous parts. When an output goes sideways, it can be harder to tell whether it was your prompt or a locally “wide” nucleus at a specific step.
Top‑k, min‑p, and cutoffs that tame extremes
A model may produce consistent results for several paragraphs, then suddenly introduce an unusual name, an overdramatic phrase, or an obscure edge case that does not fit the context. These detours can occur when the sampling process allows less probable tokens to compete at uncertain points. Top-k sampling limits each selection to the k most likely tokens, regardless of how many candidates top-p sampling would retain. This can reduce unexpected word choices, but setting k too low may also make creative writing repetitive and predictable.
Min-p sampling filters out candidates whose probabilities fall below a set fraction of the most likely token’s probability. The cutoff adjusts to the model’s confidence: when one option is strongly favored, fewer alternatives survive; when confidence is more evenly distributed, a wider range remains available. Some APIs also support logit bias and stop sequences to suppress known unwanted patterns, though these settings require careful tuning. A sensible approach is to change one setting at a time, test it against a fixed set of prompts, and check whether the results contain fewer outliers without losing useful variation.
Repetition penalties: fixing loops without dulling voice
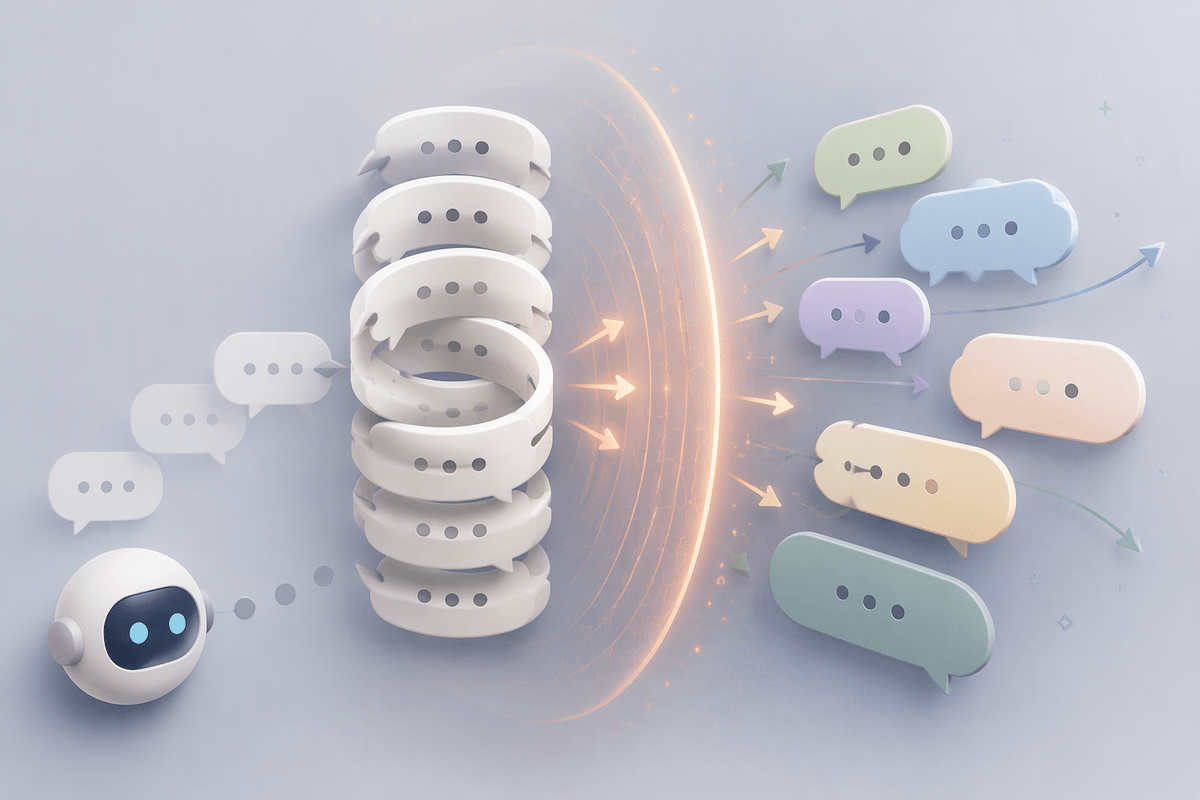
You’ve likely seen the classic loop: the model finds a phrase that works (“In summary,” “It’s important to note,” a variable name, a disclaimer) and then keeps returning to it, sometimes escalating into near-duplicate sentences. Repetition penalties are designed to push the sampler away from tokens it has already used, so the model is less likely to reuse the same words or n-grams. When they work, you get the same meaning with fresher phrasing and fewer stuck patterns.
A strong penalty can flatten deliberate repetition that’s actually useful: consistent terminology in technical docs, a product’s preferred phrasing, or a tight JSON schema where keys must repeat. It can also force awkward synonym-swapping (“latency” becomes “delay” becomes “slowness”) that hurts precision. A practical workflow is to start mild, then raise the penalty only when you observe true loops across multiple test prompts, and re-check any outputs that depend on stable wording or exact field names.
Determinism, seeds, and reproducible prompt workflows
Tuning model settings by intuition can lead to inconsistent results, especially when a configuration that worked one day performs differently the next. Reliable comparisons require keeping the test conditions as consistent as possible: use the same prompt, model, system instructions, enabled tools, truncation rules, and sampling settings. If the API supports a random seed, record it and keep it fixed during testing. This makes A/B comparisons across temperature, top-p, and penalties more meaningful. Without consistent conditions, differences in the output may come from separate sampling runs rather than the parameter being tested.
A fixed seed does not guarantee identical results in every environment. Provider updates, load balancing across model replicas, non-deterministic computation, and tools that retrieve live data can all affect repeatability. Running useful tests also requires a small evaluation set, a record of prompts and responses, and enough repeated trials to distinguish a genuine improvement from a lucky result. Keep the seed fixed while tuning, then remove it or vary it in production when greater output diversity is desirable.
Practical tuning presets and a fast adjustment loop
You’ll usually get farther with a few presets than with endless one-off tweaks. For “reliable/factual,” start low temperature (0–0.3), moderate top‑p (0.8–0.95), a small top‑k or min‑p cutoff if available, and minimal repetition penalty unless you see loops. For “balanced product copy,” use temperature around 0.5–0.8 with top‑p near 0.9, then add a mild repetition penalty only if phrasing starts echoing. For “brainstorming,” push temperature higher (0.9–1.2) and loosen cutoffs, accepting more junk.
The fast loop is: freeze a 10–20 prompt test set, lock a seed, change one knob, and score against your checklist. If outputs are off-topic, narrow sampling (lower temperature or top‑p, add cutoffs). If they’re bland, widen it (raise temperature or top‑p). If they loop, nudge repetition penalties, but re-validate any schema or terminology requirements. If you can’t rerun the same cases quickly, you’ll “tune” noise.